Medical-image machine learning
Image-based direct survival prediction
Investigating why pooled survival results weakened within individual cohorts.
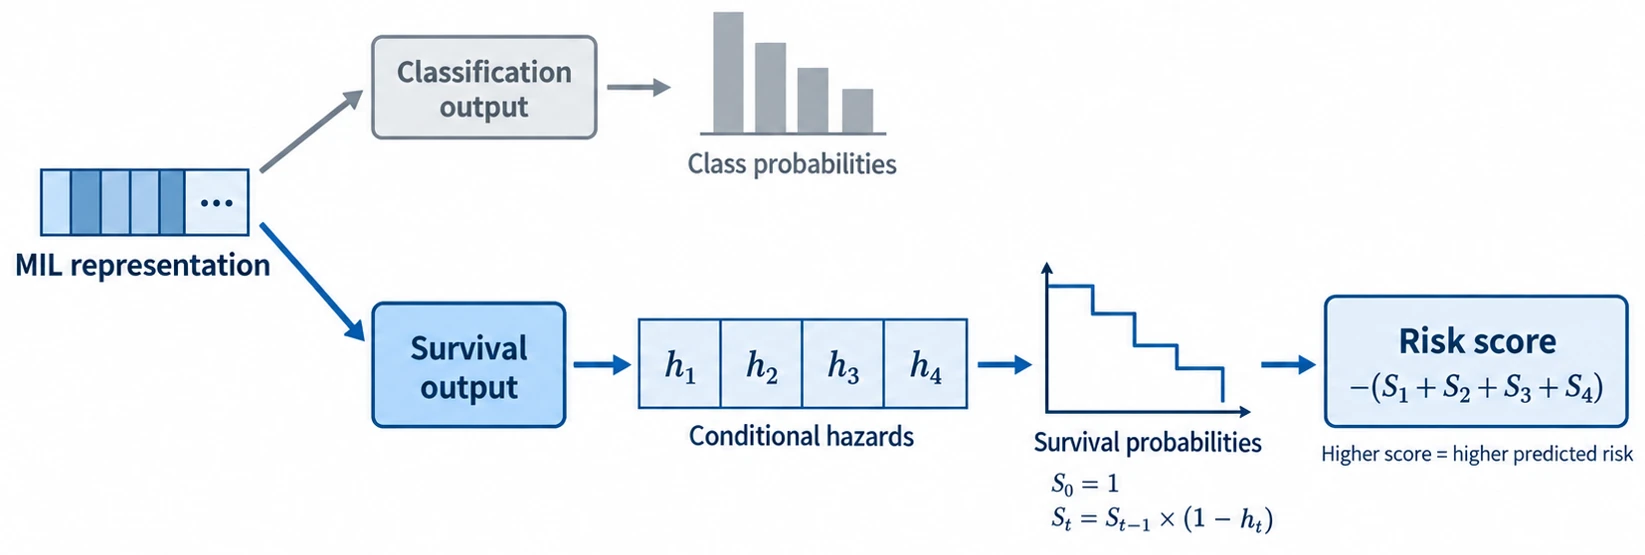
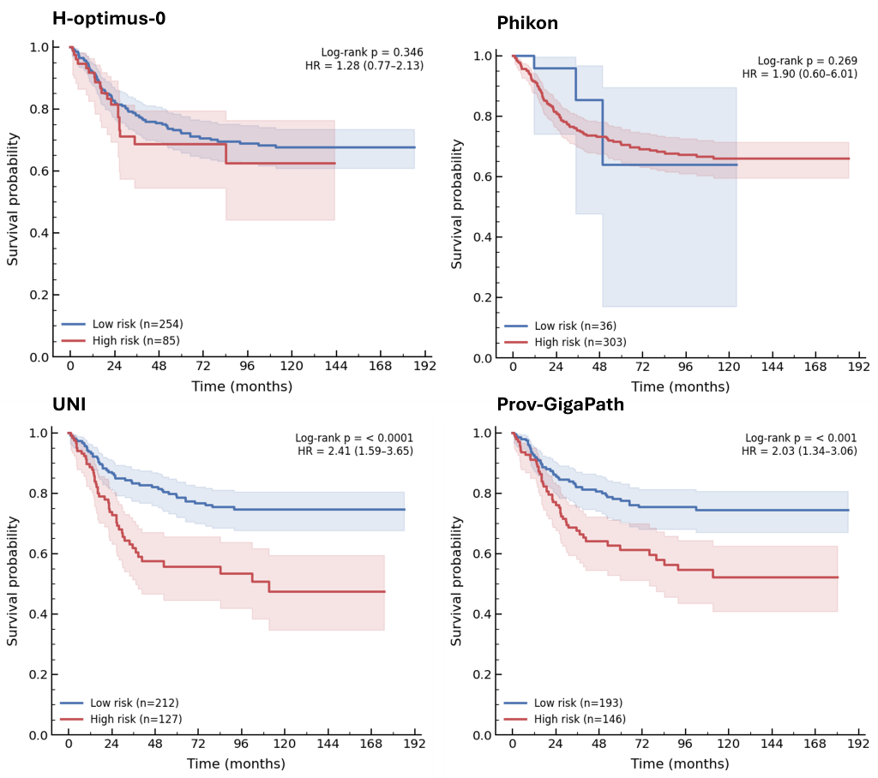
I used image representations to predict conditional event probabilities across time intervals, then derived survival probabilities and risk scores. Evaluation included the concordance index, hazard ratios and Kaplan–Meier risk-group comparisons.
Looking inside the pooled result
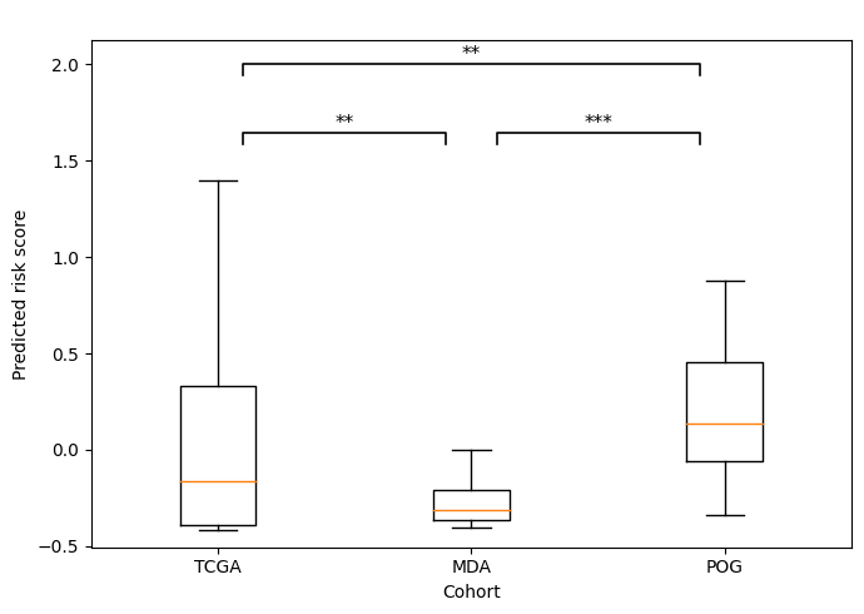
UNI and prov-GigaPath reached pooled test C-indices of 0.618 and 0.626. Performance weakened after stratifying by TCGA, MD Anderson and POG, and predicted risk differed substantially by cohort. The stronger pooled result did not establish reliable discrimination within each cohort. I examined the distribution of risk scores and associations with molecular biomarkers. These associations were weak and sensitive to cohort composition. The work illustrates why external evaluation needs to look at cohort effects as well as aggregate performance.