Computational pathology
Cancer subtype reference stability
Investigating the reliability of CMS labels.
Before training an image model to predict a molecular subtype, I wanted to understand how reliable the target labels were. This part of my thesis compared consensus molecular subtype (CMS) classifiers in colorectal cancer and examined whether their labels matched the expected biology.
A reference label depends on the protocol
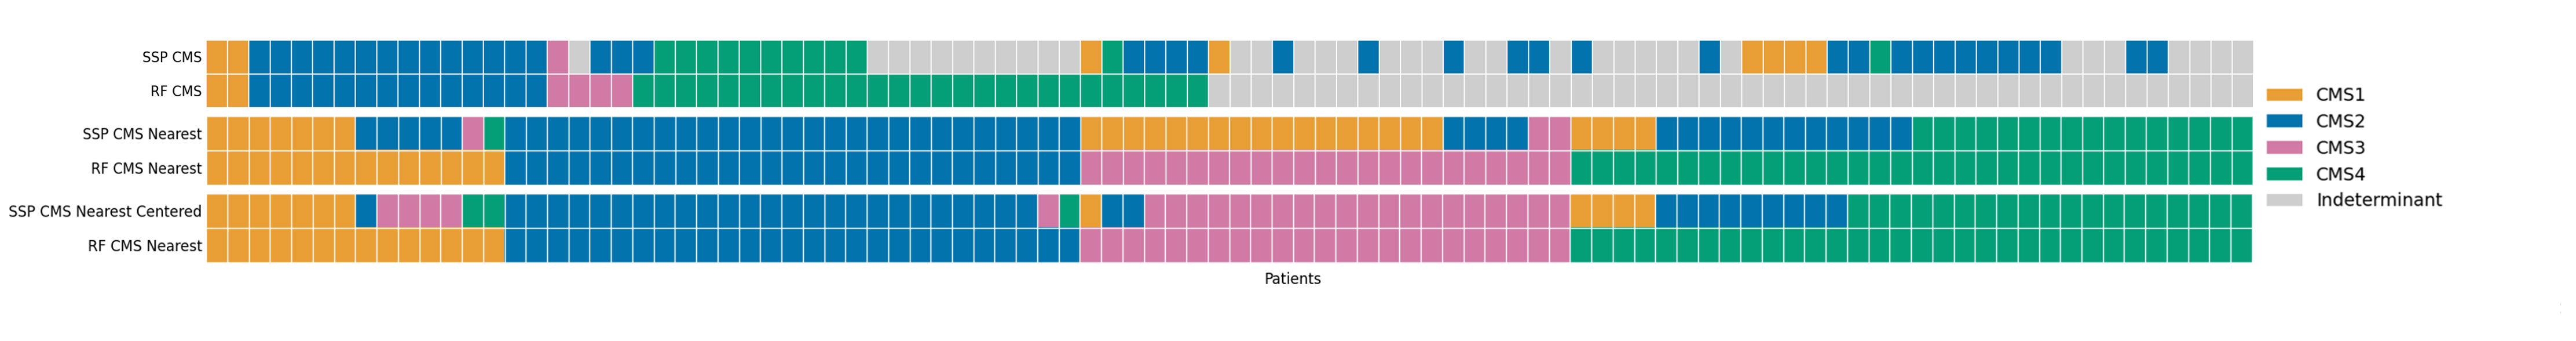
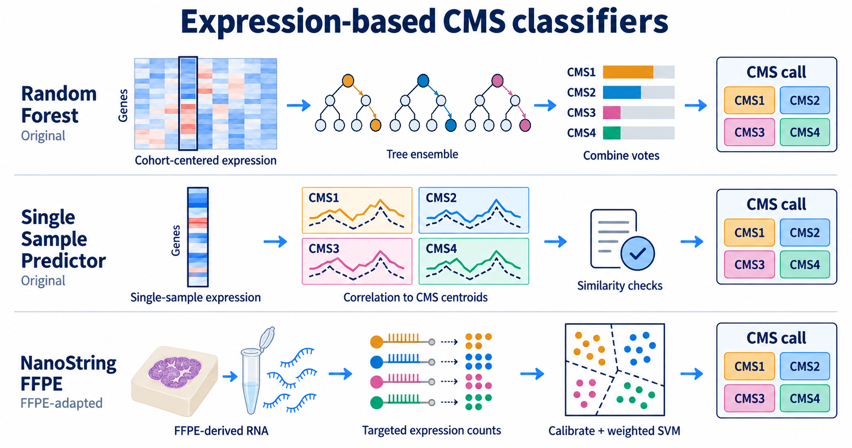
I compared Random Forest, Single Sample Predictor and NanoString FFPE approaches using gene-expression data. The analysis considered classifier agreement, indeterminate calls, and the effects of changing thresholds and preprocessing. Random Forest and Single Sample Predictor had a Cohen’s kappa of 0.56 among jointly classified cases, but agreement fell to 0.28 when indeterminate calls were retained. Changing settings within a classifier also changed the assignments, and literature methods varied. These choices affect what an image model is being asked to learn.